AI agents choose their next step through a repeating cycle of planning, tool use, and feedback. This guide explains that process, common failure points, and practical ways to keep agent decisions reviewable and safe.
When an AI agent finishes a task without anyone telling it each step, something is deciding what to do next. That decision process is where agents succeed or fail, and it is the part most product descriptions skip.
This article walks through how an agent chooses actions, how it turns a goal into finished work, what makes those choices go wrong, and how businesses can keep a handle on the results.
If you are new to the basics, a primer on How AI Agent Works covers the building blocks. Here the focus is narrower: the reasoning and the mechanics of getting from request to result.
What “Making a Decision” Means for an AI Agent
An agent does not decide the way a person does. Most current agents use a large language model (LLM) as the reasoning engine. Given a goal, the instructions it has been handed, and the information gathered so far, the model predicts the most appropriate next step. That step might be calling a tool, asking the user a question, or declaring the task complete.
So a “decision” is really a choice among available options, made repeatedly. The options are bounded by what the agent has been given: the tools it can call, the data it can read, and the rules it must follow. An agent with access to a calendar and email can schedule a meeting.
One with only a search tool cannot, no matter how capable the model is. Much of what looks like intelligence in an agent is the quality of its options and constraints.
The Decision Cycle, Step by Step
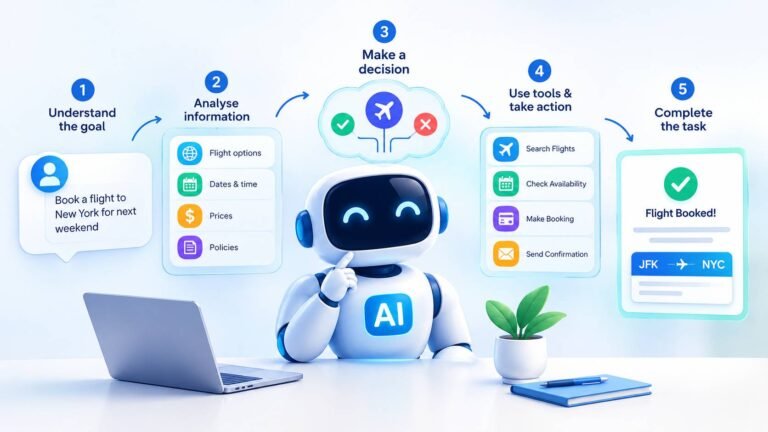
Most agents repeat a version of the same cycle until the work is done or a limit is reached.
1. Interpreting the goal
The agent first works out what is being asked. Requests are often vague (“get me ready for tomorrow’s client call”), so the agent has to infer what ready means: pull recent emails, summarize the account history, check open support tickets. Well-built agents ask a clarifying question when the ambiguity is large and proceed when it is small. Agents that never ask tend to guess confidently, which is a common source of errors.
2. Planning
Next comes a plan, sometimes explicit and sometimes implied. For simple tasks the plan is one action. For longer ones, the agent breaks the goal into subtasks and orders them. Some agents write the plan out before starting, then revise it as results come in. Others decide one step at a time without a written plan. Written plans are easier to inspect and audit, which matters in regulated work.
3. Choosing an action and a tool
At each step the agent selects from the tools it has been given. Each tool comes with a description of what it does and what inputs it needs, and the model matches the situation to the best fit. If the task requires current account balances, it should call the billing system rather than answer from general knowledge. Choosing the wrong tool, or inventing inputs the tool never asked for, is one of the more frequent failure points.
4. Acting and observing
The tool runs, and the result goes back to the agent as new information. This feedback is what separates an agent from a one-shot answer. If a database query returns nothing, the agent can adjust the search. If an API returns an error, it can retry with different parameters or report the problem.
5. Deciding whether to continue
After each observation the agent decides whether the goal has been met, whether more work is needed, or whether it should stop and hand off to a person. Well-designed systems also set hard limits on the number of steps, the time spent, or the cost incurred, so a confused agent cannot loop indefinitely.
How Agents Weigh Options and Handle Tradeoffs
Agents face tradeoffs constantly: speed versus thoroughness, cost versus accuracy, caution versus completion. They do not calculate these the way a spreadsheet would. In LLM-based agents, the tradeoffs come largely from the instructions and examples the builder provides.
A support agent told to prioritize accuracy over speed will check more sources before replying. One told to resolve tickets quickly will answer sooner and escalate less. Some systems add explicit scoring. A routing agent might rank candidate actions by estimated confidence, or a second model might review the first one’s proposed action before it runs.
Classic AI research describes this as utility-based decision-making, where each outcome is assigned a value and the agent picks the highest. In business products, the equivalent is usually a mix of rules, thresholds, and review steps rather than a pure mathematical formula.
Memory and Context: What the Agent Knows When It Decides
A decision is only as good as the information behind it. Agents draw on several sources:
- The current conversation and task history, which show what has already been tried.
- Retrieved documents, pulled from a knowledge base or file store when needed, so the agent works from your policies rather than general training data.
- Stored memory, such as saved preferences or notes from earlier sessions.
- Live tool results, which reflect the current state of your systems.
There is a practical limit. Models can only consider a limited amount of text at once, so long tasks require the agent to summarize or discard older details. When key information drops out, decisions degrade. Teams that notice an agent “forgetting” instructions midway through a long job are usually seeing this limit at work.
A Worked Example: Handling a Billing Dispute
Consider a hypothetical customer support agent at a US utility company. A customer writes in claiming a charge is wrong. This is an illustrative scenario, not a description of any specific product.
The agent reads the message and identifies the goal: resolve or route a billing dispute. It looks up the account and finds the charge. It checks the billing policy document and sees that charges over a certain amount require supervisor review.
It decides this case is over the threshold, so it does not issue a credit itself. Instead it drafts a summary for a human supervisor, attaches the account history, and sends the customer a message explaining what happens next.
Notice where the decisions happened: choosing which systems to check, applying a policy rule, and choosing to escalate instead of act. The last one is the important one. A good agent knows the limits of its authority.
Where Agent Decisions Go Wrong
Understanding the failure modes helps you design around them.
- Plausible but wrong reasoning. LLMs can produce a confident chain of logic built on a false assumption. Verification steps, such as checking facts against a trusted source before acting, reduce the risk.
- Compounding errors. A wrong early step can steer every later one. The longer the task, the more this matters.
- Poor tool choices. Vague tool descriptions or too many overlapping tools make the agent more likely to pick the wrong one.
- Manipulated input. Text in an email, web page, or document can contain instructions meant to hijack the agent, a risk usually called prompt injection. Limiting permissions and treating external content as untrusted both help.
- Overconfidence at the edges. Agents often perform well on common cases and poorly on unusual ones, without signaling the difference.
Keeping Agent Decisions Under Control
Control comes from design choices made before launch, not from hoping the model behaves.
- Define clear boundaries. Specify what the agent may do on its own, what needs approval, and what is off limits. Actions involving payments, legal commitments, or sensitive records generally belong in the approval category.
- Keep humans in the loop where stakes are high. Review queues, confirmation prompts, and escalation paths are standard.
- Log everything. Record the inputs, the tools called, and the outputs so you can trace why a decision was made and fix patterns of error.
- Test on your own cases. Vendor demos use clean examples. Run the agent on real, messy ones, including edge cases and adversarial inputs.
- Apply a risk framework. The NIST AI Risk Management Framework is a voluntary US resource for identifying and managing AI risks, and it is a reasonable template for internal review.
Considerations in healthcare
In healthcare settings, agent decisions can touch protected health information, so HIPAA obligations apply to covered entities and their business associates. The HHS page on the HIPAA Security Rule outlines the baseline safeguards. If an agent’s output influences clinical decisions in a way that meets the definition of a medical device, the FDA may also have a role, and the agency maintains information on AI- and machine learning-enabled medical devices. Whether these rules apply to a specific tool depends on what it does and who uses it, so compliance and legal teams should make that determination rather than relying on vendor claims.
Choosing an Agent: What to Ask About Its Decision-Making
Before adopting an agent, ask questions that expose how it decides:
- What tools can it call, and can those permissions be limited?
- Can I see its reasoning or action log for any given task?
- Which actions require human approval, and can I change that?
- What happens when it is unsure or a tool fails?
- How does it handle conflicting or missing information?
- How is pricing structured? Per user, per task, and per token charges behave very differently once an agent makes many calls per job, so it helps to compare ai tool pricing models before signing.
Browsing an AI Agent Marketplace can also help you compare agents by function and see how different vendors describe their tools and controls before you run a pilot.
Frequently Asked Questions
How does an AI agent decide what to do next?
It uses a reasoning model, usually an LLM, to pick the next action based on the goal, its instructions, the tools available, and the results so far, then repeats the process until the task is done.
Do AI agents think for themselves?
Agents make choices within limits set by their builders. They do not have independent goals; they work toward the objective and rules they were given.
Why do AI agents make mistakes?
Common causes include wrong assumptions, unclear instructions, poor tool selection, missing context, and manipulated input. Mistakes can compound across steps.
Can an agent complete tasks without human involvement?
Some can, for low-risk work. For tasks involving money, legal matters, customer commitments, or health data, most organizations keep a person in the approval path.
How do I know why an agent did something?
Choose systems that log tool calls, inputs, and outputs. Without logs, it is difficult to audit or correct behavior.
Are AI agents safe to use with patient data?
It depends on the tool, the contract, and your controls. HIPAA requirements apply to covered entities and business associates, and a business associate agreement is typically part of the picture. Verify with your compliance team.
Final Takeaways
An AI agent’s decisions come from a repeating cycle of interpreting a goal, planning, choosing a tool, observing the result, and deciding whether to continue, all shaped by the instructions, data, and permissions it has been given. Better outcomes come less from a smarter model than from clear boundaries, good information, and sensible human checkpoints.
A practical next step: pick one workflow you are considering for an agent, write down every decision a person currently makes in it, and mark each as safe to automate, needs approval, or must stay human. That list becomes your design brief and your evaluation checklist.
Published by Meedium.